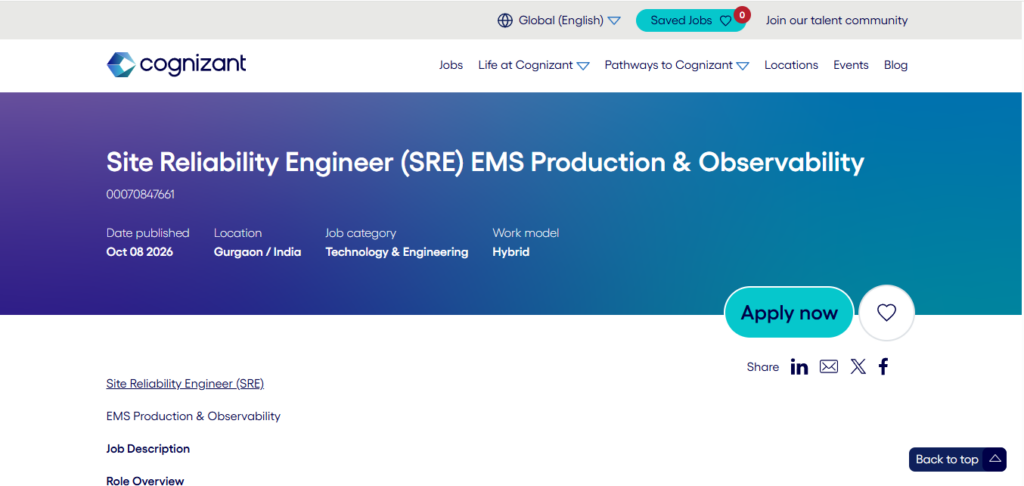
Cognizant announced job vacancy for the post of Site Reliability Engineer (SRE) – EMS Production & Observability. The place of posting will be at Gurgaon (Hybrid). Candidates who have completed Bachelor’s Degree is required with Strong experience in Site Reliability Engineering, Production Engineering, DevOps, or Production Support for enterprise-scale applications are eligible to apply. More details about qualifications, job description and roles & responsibilities are as follows
Company Overview
| Name of the Company | Cognizant |
| Required Qualifications | Graduate |
| Skills | Site Reliability Engineering, Production Engineering, DevOps, etc.., |
| Category | EMS Production & Observability |
| Work Type | Hybrid |
They are looking for an experienced Site Reliability Engineer (SRE) to support the reliability, availability, performance, and operational readiness of EMS production services. The engineer will be responsible for production support and incident resolution, enhancing ELF, building actionable operational dashboards, improving monitoring and alerting, automating repetitive operational activities, and proactively preparing the platform for high-volume/high-visibility events such as the US Open 2026.
This role requires someone who can move beyond reactive production support and use observability, automation, capacity planning, trend analysis, and engineering improvements to identify and address reliability risks before they become customer-impacting incidents.
Job Details
Θ Positions: Site Reliability Engineer (SRE) – EMS Production & Observability
Θ Job Location: Gurgaon (Hybrid)
Θ Salary: As per company standards
Θ Job Type: Full Time
Θ Requisition ID: 00070847661
Roles and Responsibilities:
- Production Reliability & Incident Management
- Own and support EMS production incidents, including investigation, triage, mitigation, recovery, and root-cause analysis.
- Participate in production support/on-call rotations and provide timely response to critical incidents.
- Troubleshoot application, infrastructure, API, integration, latency, capacity, and availability issues across the EMS ecosystem.
- Drive incidents through resolution by collaborating with application engineering, infrastructure, platform, networking, database, and dependent service teams.
- Conduct Root Cause Analysis (RCA) for significant incidents and ensure corrective/preventive actions are implemented.
- Identify recurring production problems and convert operational fixes into permanent engineering solutions.
- Observability, Monitoring & Dashboards
- Design and maintain real-time operational dashboards providing visibility into EMS health and customer-impacting conditions.
- Define and monitor key SLIs/SLOs around availability, latency, throughput, errors, and service dependencies.
- Build meaningful alerting based on customer/service impact rather than relying solely on infrastructure thresholds.
- Correlate application logs, metrics, events, and infrastructure telemetry to accelerate issue detection and troubleshooting.
- Develop dashboards for transaction/request volume, success and failure rates, response time and latency, API/service availability, infrastructure and application health, dependency health, error trends and top failure reasons, capacity/utilization, and event-specific traffic and performance.
- Continuously tune alerts to reduce noise and improve signal-to-noise ratio and Mean Time to Detect (MTTD).
- ELF Enhancement & Automation
- Enhance ELF capabilities to improve production monitoring, operational efficiency, troubleshooting, and reliability.
- Identify manual production-support activities and automate them using scripting, APIs, CI/CD, or appropriate platform capabilities.
- Build automated health checks, diagnostics, remediation, and operational reporting.
- Develop reusable operational tools and runbooks that enable faster diagnosis and recovery.
- Work with engineering teams to incorporate reliability and observability requirements into new releases.
- Major Event Readiness
- Lead proactive reliability planning for major business events such as US Open 2026 and other anticipated high-volume periods.
- Analyze historical and projected traffic patterns to identify potential capacity or performance bottlenecks.
- Establish event-specific dashboards, alerts, and operational thresholds.
- Perform capacity planning, load/performance validation, and dependency readiness assessments.
- Identify critical failure scenarios and develop mitigation and recovery plans before the event.
- Conduct pre-event readiness reviews, failure simulations/game days, and operational rehearsals.
- Establish clear event-day monitoring, escalation paths, communication channels, and incident-response procedures.
- Produce post-event analysis covering performance, incidents, trends, and opportunities for improvement.
Required Skills & Qualifications:
- Strong experience in Site Reliability Engineering, Production Engineering, DevOps, or Production Support for enterprise-scale applications.
- Strong hands-on production troubleshooting and incident-management experience.
- Experience building production monitoring, alerting, and observability dashboards.
- Strong understanding of application and infrastructure metrics, logs, distributed services, and API monitoring.
- Experience with cloud infrastructure and containerized environments.
- Knowledge of Kubernetes, CI/CD, Infrastructure as Code, and automation.
- Scripting/programming experience with Python, Bash, PowerShell, or equivalent.
- Understanding of networking concepts including DNS, load balancing, firewalls, routing, and connectivity troubleshooting.
- Experience performing RCA and driving preventive engineering actions.
- Ability to analyze traffic, latency, errors, and capacity trends and translate findings into engineering improvements.
- Strong communication skills and ability to coordinate effectively during high-severity production incidents.
Preferred Qualifications
- Experience with Azure, AKS/Kubernetes, Terraform, GitHub Actions, Grafana/Prometheus, Splunk or equivalent observability platforms, Application Performance Monitoring (APM), synthetic monitoring, automated remediation, chaos/game-day testing, and high-volume event readiness would be valuable.
- Experience supporting highly available, customer-facing platforms where reliability during major events and peak traffic periods is critical is strongly preferred.
How to Apply
Apply Link – Click Here
For Regular Updates Join our WhatsApp – Click Here
For Regular Updates Join our Telegram – Click Here
Disclaimer:
The information provided on this page is intended solely for informational purposes for Students, Freshers & Experience candidates. All the recruitment details are sourced directly from the official website and pages of the respective company. Latest MNC Jobs do not guarantee job placement, and the recruitment process will follow the company’s official rules and Human Resource guidelines. Govtjobmart do not charge any fees for sharing job information. Latest MNC Jobs strongly advise Students, Freshers & Experience candidates not to make any payments for any job opportunities.
